tomsguide.com
Cast the first vote in 1 tap — pick #1 Claude Fable 5.2 or #2 Gemini 4 Carbon to reveal the live split:
Fable 5.2 leads Intelligence Index v5 at 64.6 and 79% accuracy, while Gemini 4 Carbon costs 4x less per token and tops Arena Text. Fable 5.2 leads Intelligence Index v5 at 64.6 and 79% accuracy, while Gemini 4 Carbon costs 4x less per…
token and tops Arena Text. Overall Intelligence & Reasoning #1: Claude Fable 5.2 (93.9 BenchAlign v5.8 / 64.6 Intelligence Index v5). Agentic Coding & WebDev #1: Claude Opus 5.5 (1818 Arena WebDev / 65.8% Terminal-Bench 4.1). Open-Weight Leader #1: Kimi K3.1 Pro (70.4 BenchAlign v5.8 / 67.2% Terminal-Bench 4.0). Fable 5.2 leads Intelligence Index v5 at 64.6 and 79% accuracy, while Gemini 4 Carbon costs 4x less per token and tops Arena Text. Overall Intelligence & Reasoning #1: Claude Fable 5.2 (93.9 BenchAlign v5.8 / 64.6 Intelligence Index v5). Agentic Coding & WebDev #1: Claude Opus 5.5 (1818 Arena WebDev / 65.8% Terminal-Bench 4.1). Open-Weight Leader #1: Kimi K3.1 Pro (70.4 BenchAlign v5.8 / 67.2% Terminal-Bench 4.0). Evaluated across Intelligence Index v5, BenchAlign v5.8, ARC-AGI-3, FrontierCode 2.0, LiveBench 2.0, token pricing, and context window capacity as of November 2026.
tomsguide.com
Starting order. Vote up or down to reorder this list.
Think something was robbed of a spot?
Nominate a missing contender — once approved, the community votes it up or down into the rankings.
Released Nov 9, 2026, Claude Fable 5.2 holds #1 on BenchAlign v5.8 (93.9), Intelligence Index v5 (64.6 at max effort), AA-Omniscience accuracy (79%), Humanity's Last Exam (74.3%), ARC-AGI-3 (81.2%), FrontierCode 2.0 (49.1%), and LiveBench 2.0 (84.9). It beats #2 Gemini 4 Carbon by 4.6 points on Intelligence Index v5, though Carbon costs 4x less per token at $2/$10.
GA since Nov 10, 2026, Gemini 4 Carbon ranks #1 in Arena Text (1526), Mercor APEX-Agents (84.2%), and LiveBench 2.0 Coding (91.0), plus #2 on Terminal-Bench 4.0 (65.2%). It trails #1 Claude Fable 5.2 by 4.7 BenchAlign points, yet edges #3 Claude Opus 5.5 by 0.9 points on Intelligence Index v5 while matching half of Opus 5.5's standard $4/$20 API rate through Nov 30.
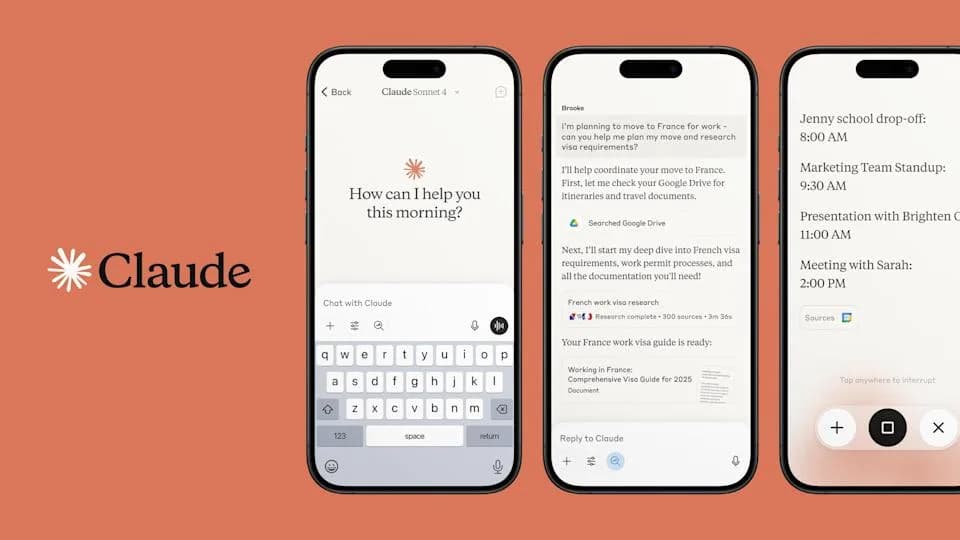
Launched Sept 22, 2026, Claude Opus 5.5 leads Arena WebDev (1818), image-to-WebDev (1750), Terminal-Bench 4.1 (65.8%), Mercor APEX-SWE (67.6%), and GDPval-AA v2.1 (1866), alongside #2 on Humanity's Last Exam (61.4%). It sits 2.6 BenchAlign points behind #2 Gemini 4 Carbon, but outscores #4 GPT-6 Astra by 2.2 points on Intelligence Index v5 at less than half Astra's $10/$50 price.
OpenAI's Sept 3, 2026 flagship tops ARC-AGI-2 at 95% and ranks #2 on both LiveBench 2.0 Reasoning (92.7) and ARC-AGI-3 (62.7%), plus #4 on Arena WebDev (1767). It trails #3 Claude Opus 5.5 by 2.2 points on Intelligence Index v5 and costs $10/$50 per 1M tokens, yet leads sibling #5 GPT-6.1 Sol by 2.3 points on Intelligence Index v5.
Released Sept 29, 2026, GPT-6.1 Sol hits 54.6 on Intelligence Index v5 at $1.27 per task—the lowest cost among models above 50—with #2 on ARC-AGI-2 (94.2%), #3 on LiveBench 2.0 Reasoning (92.6), and 60.9% on Terminal-Bench 4.1. It lags #4 GPT-6 Astra by 1.1 BenchAlign points at 5x lower token pricing, and tops #6 Claude Sonnet 5.5 by 1.5 BenchAlign points.
Available free on claude.ai, Claude Sonnet 5.5 places #2 on Arena WebDev (1774), Terminal-Bench 4.1 (63.9%), and Mercor APEX-SWE (66.4%), plus #4 on GDPval-AA v2.1 (1838). It trails #5 GPT-6.1 Sol by 0.4 Intelligence Index points overall, but leads #7 Gemini 4 Argon by 4.0 BenchAlign points and 3.8 Intelligence Index points.
GA since Oct 13, 2026 on AI Pro and API, Gemini 4 Argon leads Arena Creative Writing (1525) and LiveBench 2.0 Reasoning (95.1), ranks #2 in Arena Text (1522) and Mercor APEX-Agents (82.4%), and posts a 4% AA-Omniscience hallucination rate. While 3.8 Intelligence Index points behind #6 Claude Sonnet 5.5, it beats #8 GPT-6.1 Terra on Arena preference and reasoning.
Launched Oct 26, 2026, GPT-6.1 Terra scores 51.3 on Intelligence Index v5 at $0.96 per task and $1/$5 per 1M tokens, with #3 on LiveBench 2.0 Coding (89.2), #4 on FrontierCode 2.0 (42.3%), and 55.6% on Terminal-Bench 4.0. It trails #7 Gemini 4 Argon on Arena preference and hallucination rate, but beats #9 Muse Wonder Full by 7.0 BenchAlign points.
Released Oct 12, 2026 inside Muse Code, Meta's Muse Wonder Full reaches #3 on GDPval-AA v2.1 (1857), 57.1% on Terminal-Bench 4.0, and #7 on Arena WebDev (1724) with a 50.1 Intelligence Index v5 score. It sits 1.2 Intelligence Index points behind #8 GPT-6.1 Terra and 7.0 BenchAlign points back, while beating #10 Kimi K3.1 Pro by 3.6 Intelligence Index points.
With open weights published Nov 2, 2026, Moonshot AI's 2.8T-total / 104B-active parameter Kimi K3.1 Pro leads all open-weight models by 13.9 Intelligence Index points over DeepSeek V4.1-Flash-1017, hits #1 overall on AA's Terminal-Bench 4.0 run (67.2%), #2 on GDPval-AA v2.1 (1861), and #2 on EQ-Bench Creative Writing (2172.6). It trails #9 Muse Wonder Full by 3.6 Intelligence Index points.
Have a list idea?
Start your own list and get help drafting entries with AI. A free account is required.
Create a list with AI →Debating whether #1 Claude Fable 5.2 holds the top spot against #2 Gemini 4 Carbon.
The published order is the starting point; item votes can help reshape it.
Rank Scramble: Can You Order Today's Top 10?
Drag ten shuffled picks into their live community order in under 60 seconds.
Rank it your way
Remix this list into your own ranking, or head to the play hub for every game mode and community breakdown — blind mode, challenges, tier lists, and more.
#1 Sony WH-1000XM6 · #2 Apple AirPods Max 2 · #3 Bose QuietComfort Ultra Headphones
Explore this ranking →
#1 The Metaverse · #2 Web3 / Blockchain · #3 NFTs
Explore this ranking →
#1 VS Code · #2 Blender · #3 Linux (Ubuntu)
Explore this ranking →